Introducing the Microsoft Copilot harness in Foundry Agent Service
Today, we’re introducing the Microsoft Copilot harness in Foundry Agent Service in public preview.
The
Having visibility into your network traffic is essential to operating Kubernetes environments effectively. When a service slows down or loses connectivity, knowing who is talking to whom lets you narrow the problem down quickly. In a standard cloud network, flow logs provide that view by recording connections between IP addresses, ports, and protocols. In Kubernetes, however, pods are temporary. Their IP addresses change constantly as pods scale, crash, or move between nodes, so a raw log entry showing 10.4.2.18 talking to 10.4.8.44 tells you little about which workload (and pod) owned that address, what namespace it was in, or what application it was trying to reach. By the time you search your cluster, the pod may already be gone!
In a Google Cloud environment, VPC Flow Logs closes this gap at the network layer. Google Cloud’s virtual network already sees every connection a pod makes, so each sampled flow is recorded with the Google Kubernetes Engine (GKE) metadata behind the IP address: pod, workload, namespace, and service. You get workload-level attribution for L3/L4 traffic without deploying extra agents or sidecars, and it complements in-cluster Container Network Interface (CNI) and dataplane observability tools you may already run when you need deeper detail. Let’s take a deeper look at how VPC Flow Logs and GKE work together, and how to get started with it.
VPC Flow Logs samples traffic directly inside Google Cloud’s virtual network. When flow logs are enabled for a subnet that hosts a GKE cluster, every record of pod traffic that passes through the VPC network is annotated with the Kubernetes context that owned the IP address at the time of sampling. This helps ensure the context is preserved even after the pod is gone:
Cluster: The cluster name and location.
Workload: The pod name and namespace, along with the controller that owns the pod, such as a deployment, StatefulSet, or DaemonSet.
Service name: The Kubernetes service that received the traffic.
Node and zone: The standard VPC fields, including the node VM and its zone on both ends of the flow.
If you register your GKE workloads in App Hub, each record also carries application-level labels (apphubSource and apphubDestination) that identify the business application, environment, and criticality of each endpoint. This is especially useful when GKE microservices talk to App Hub-registered resources outside the cluster, such as Cloud Run services.
Upgrade your log bucket to Observability Analytics (formerly Log Analytics): Flow Analyzer reads only from an upgraded bucket, typically _Default. Note: This upgrade is permanent.gcloud logging buckets update _Default --location=global --enable-analytics
Enable VPC Flow Logs organization-wide: One organization-level configuration covers every subnet in every VPC network, including future clusters (requires Network Management Admin role). Keep include-all-metadata on so every record carries namespace and pod details. To balance visibility against cost, you can add a secondary sampling rate (--flow-sampling), an aggregation interval (--aggregation-interval), or a filter expression (--filter-expr) to view only the traffic of interest.gcloud network-management vpc-flow-logs-configs create CONFIG_NAME --location=global --organization=ORGANIZATION_ID --metadata=include-all-metadata
Turn on intranode visibility: Autopilot clusters already have it, but you need to enable it on Standard clusters. Note: Enabling it restarts control plane and node components and adds some per-node overhead, so test it on a non-production cluster first.gcloud container clusters update CLUSTER_NAME --location=LOCATION --enable-intra-node-visibility
Now you’re ready to get started.
VPC Flow Logs write every record to Cloud Logging, you can search and query it in Logs Explorer or Log Analytics. For day-to-day work, Flow Analyzer, part of Network Intelligence Center, turns the same records into an interactive chart and table, so you can group and filter traffic by cluster, namespace, workload, pod, or service in a few clicks.
The walkthroughs below use Online Boutique, an open-source microservices demo, on a GKE Autopilot cluster in us-central1. A loadgenerator deployment sends synthetic shopper traffic to the frontend, which calls productcatalogservice, cartservice, currencyservice, recommendationservice, shippingservice, adservice, and checkoutservice.
Case 1: Turn IP addresses into workload names
Whether you’re investigating an incident or assessing an architecture change, the first question is always the same: Which endpoints are communicating, and at what volume?
Rather than presenting ephemeral IP address pairs, GKE metadata allows Flow Analyzer to answer this question directly using Kubernetes workload names.
Steps in Flow Analyzer:
Open Network Intelligence Center > Flow Analyzer and set the time range to last 1 hour.
Under Source and Destination, set Organize flows by to GKE workload.
In the filter bar, add the GKE workload is known filter so only pod-to-pod traffic is shown.
Click Run new query.
Grouping traffic by Source GKE workload and Destination GKE workload in Flow Analyzer to map microservice dependencies without raw IP lookups.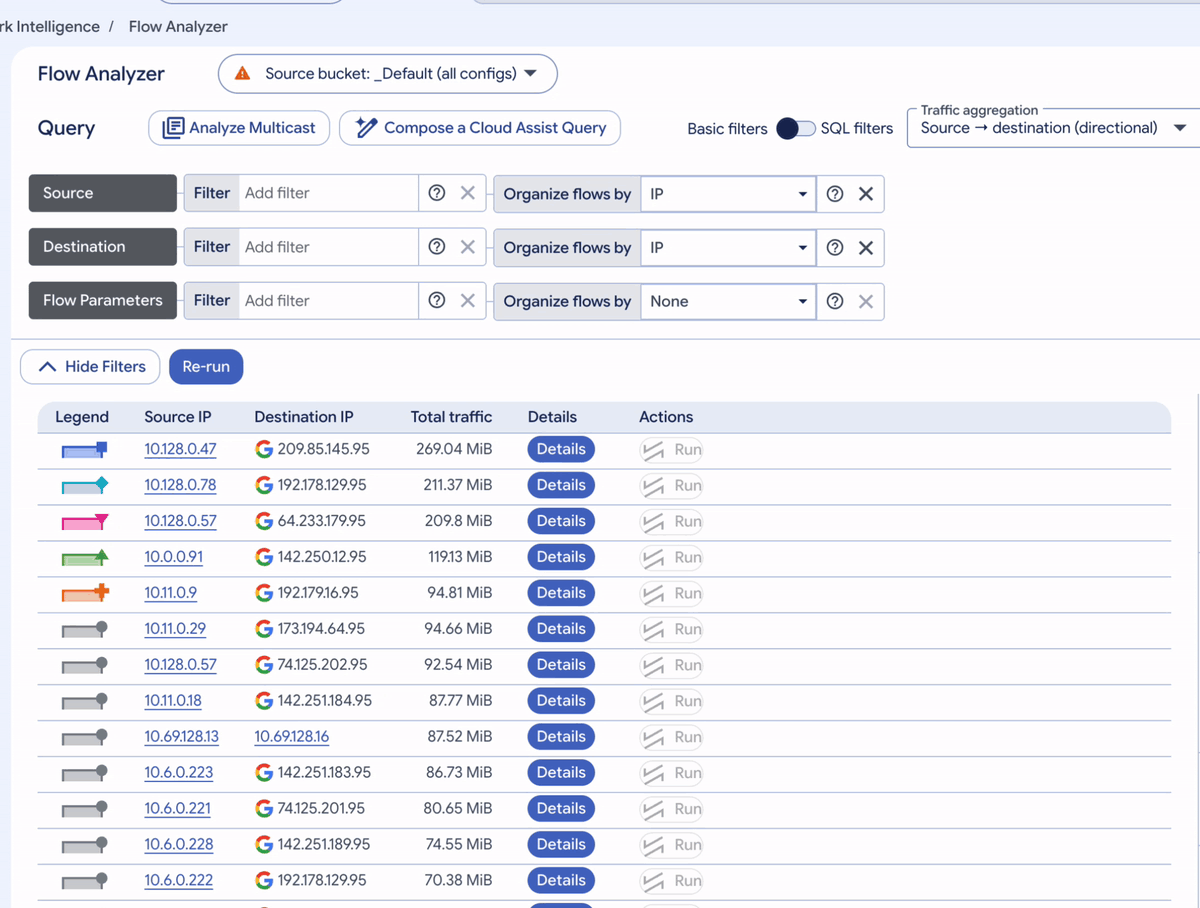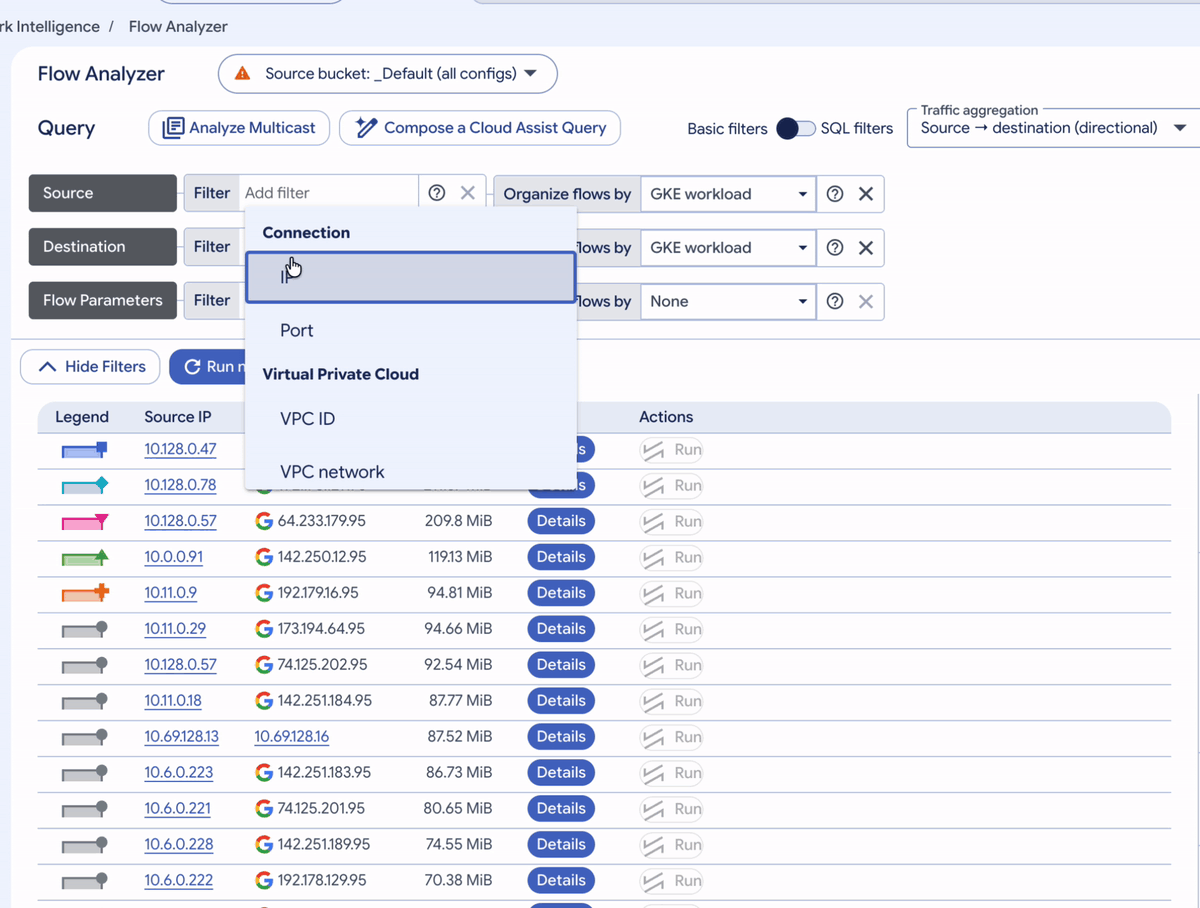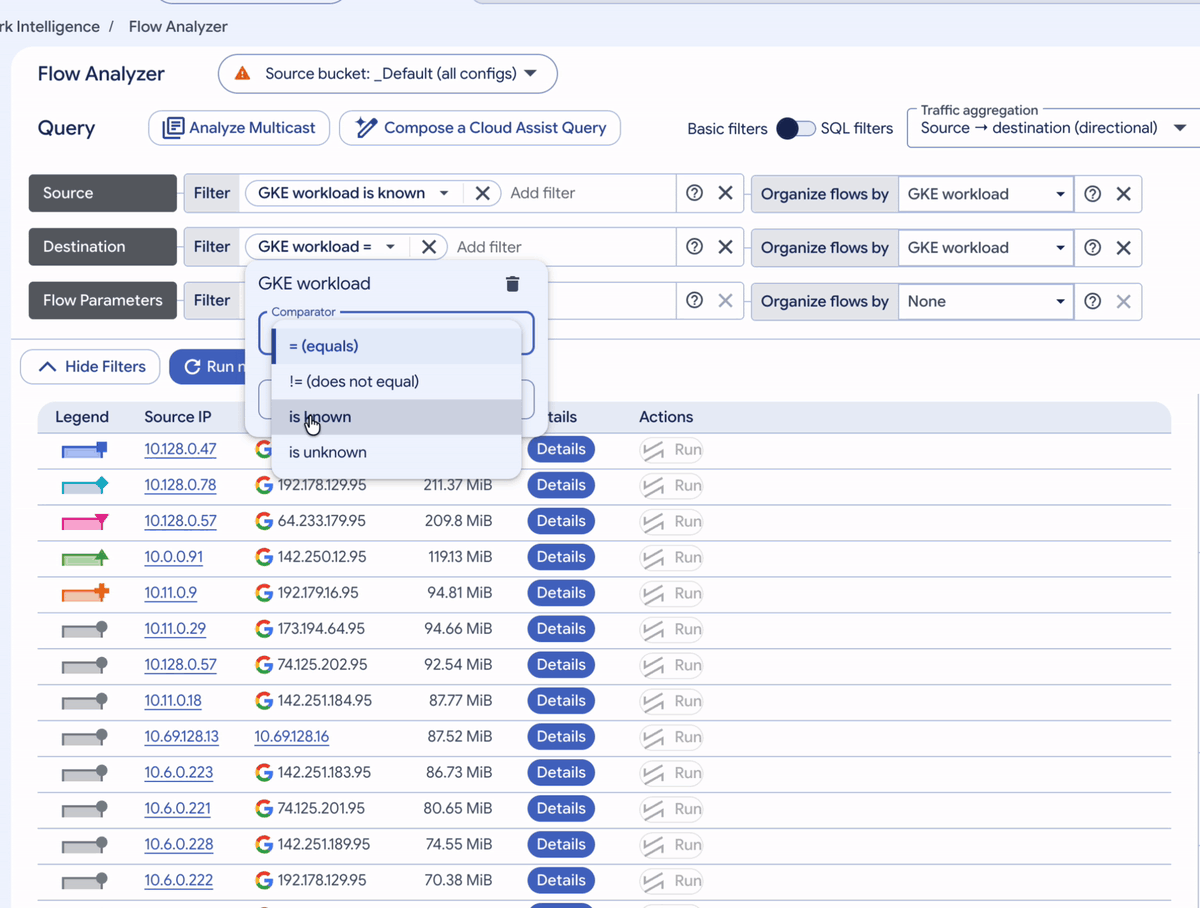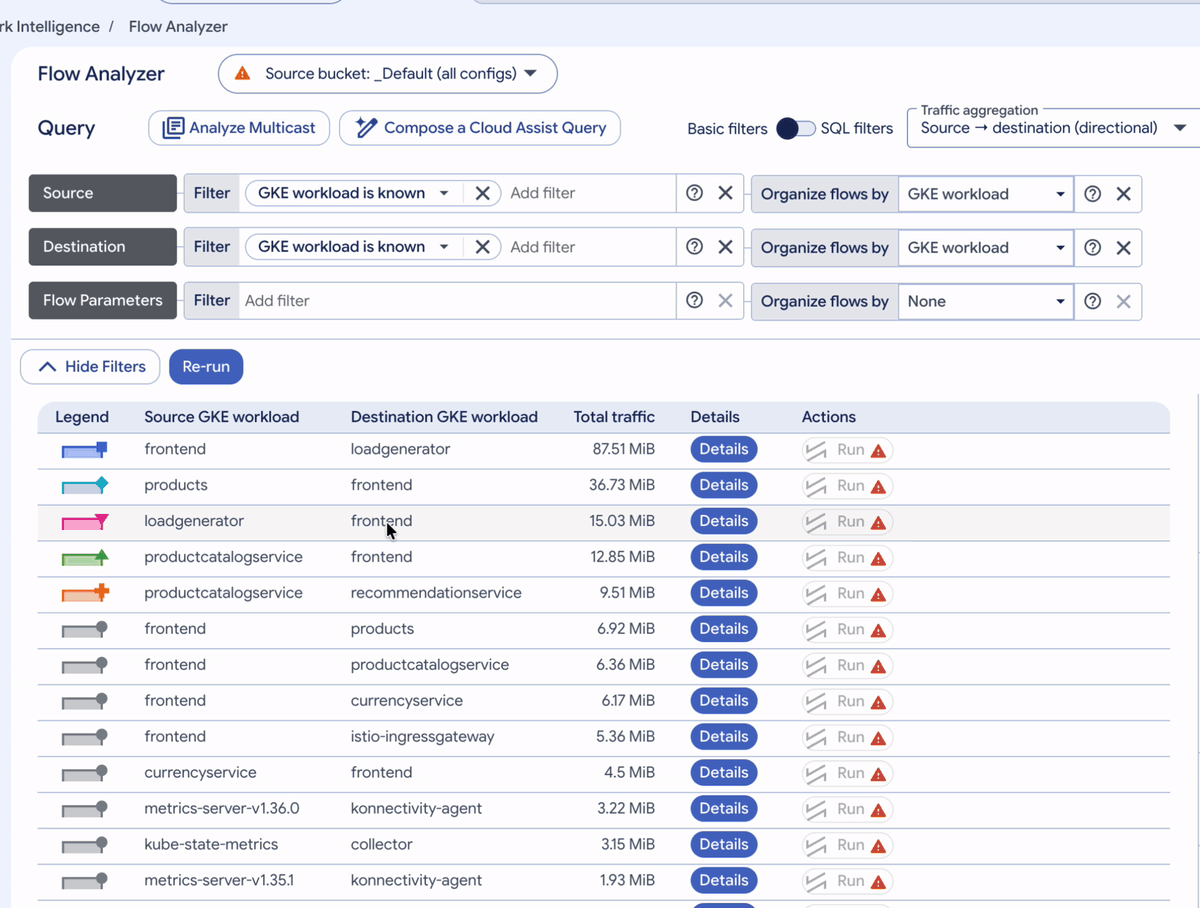
Key insights: Sorted by volume, the table is a ready-made application dependency map: frontend handles incoming requests from loadgenerator (representing user traffic), while productcatalogservice answers calls from both recommendationservice and frontend. Because each row shows workload names instead of raw IP addresses, any unauthorized or unexpected workload-to-workload communication immediately becomes apparent.
Case 2: Drill into a single service
When a service is slow or about to change, you need to know who depends on it and how heavily.
Steps in Flow Analyzer:
Change Traffic aggregation to Client ↔ server (bidirectional), so requests and responses between a pair are counted together.
Under Server, add the filter GKE workload = productcatalogservice.
Click Run new query, then click Details on the top row.
Filtering on Server GKE workload (productcatalogservice) with Client ↔ server (bidirectional) aggregation to view caller share and the Details timeline.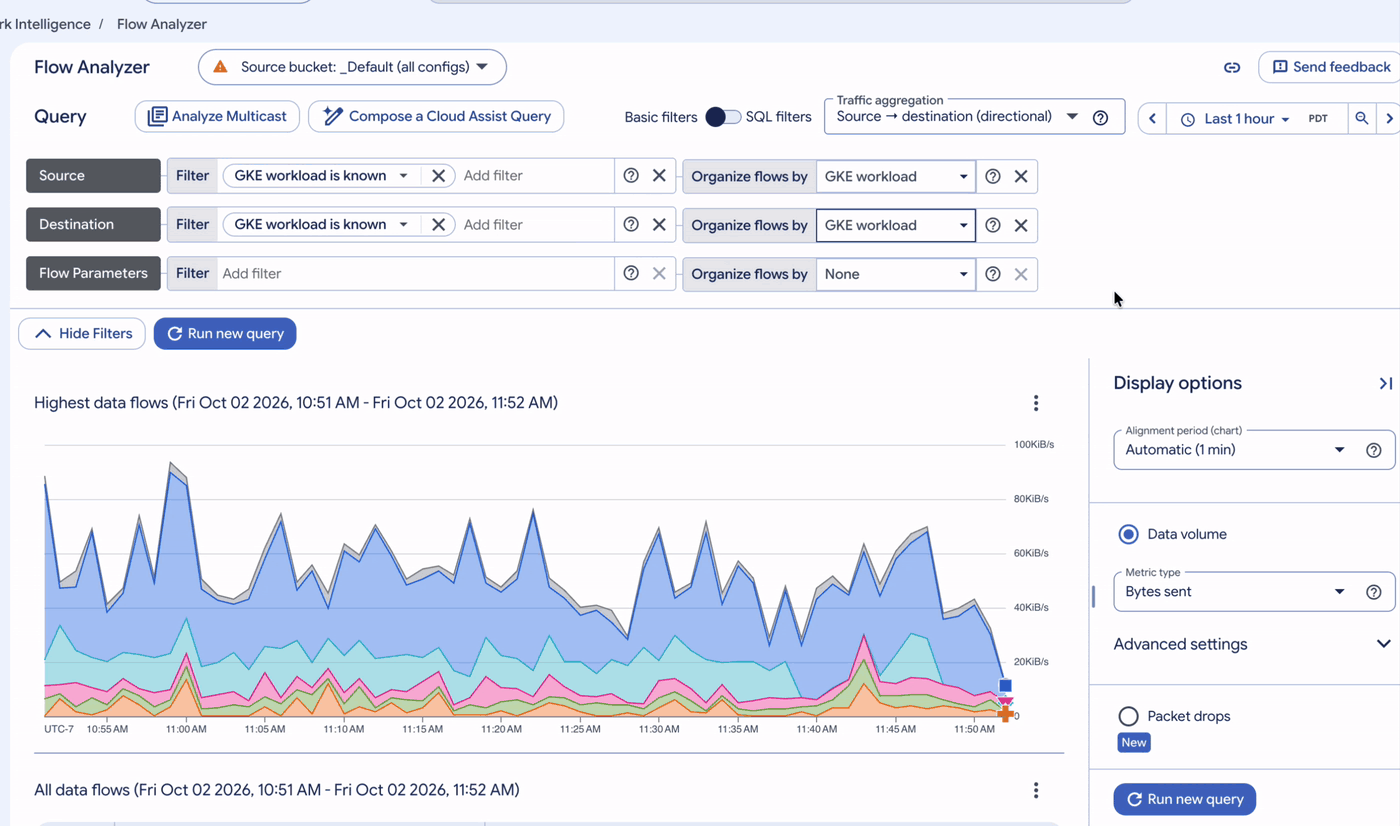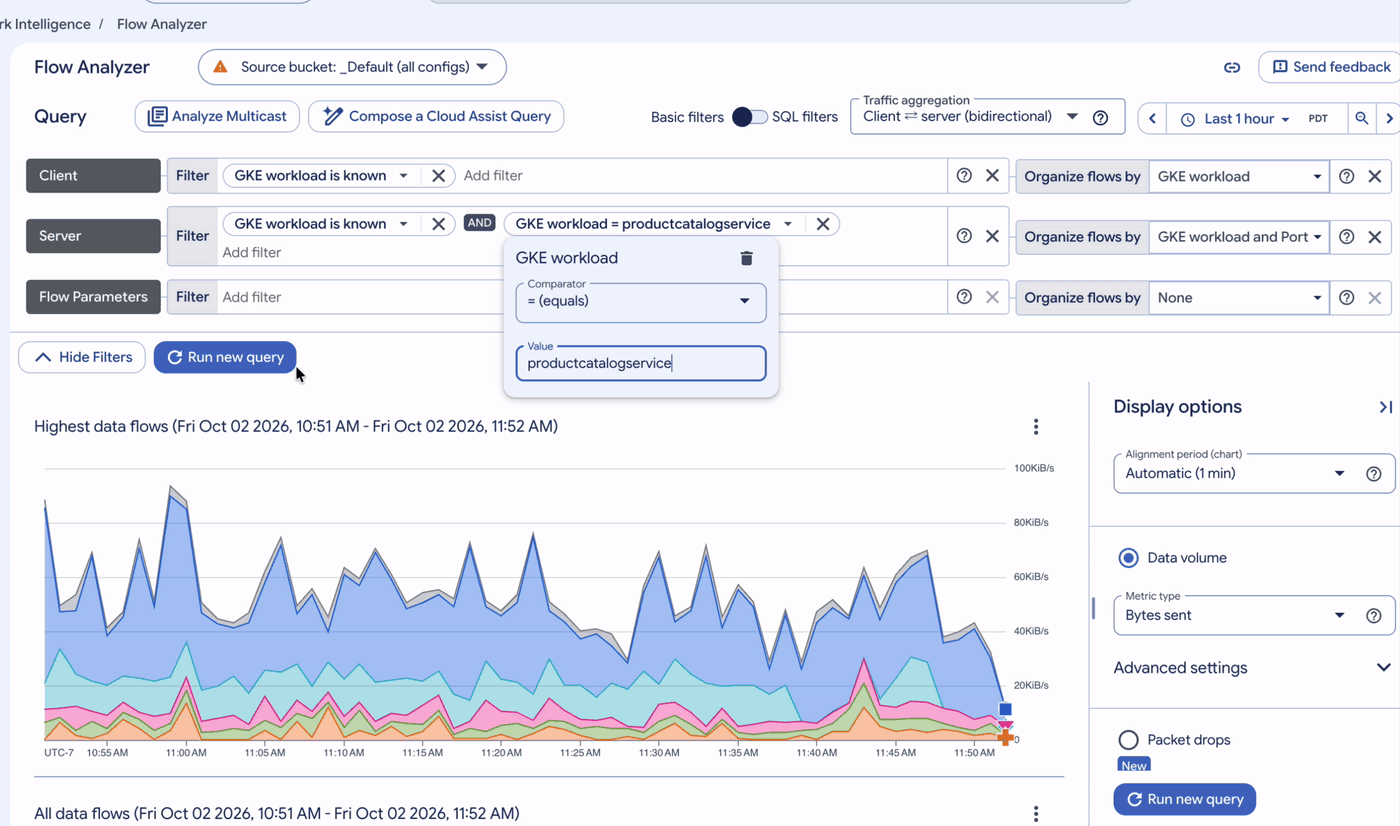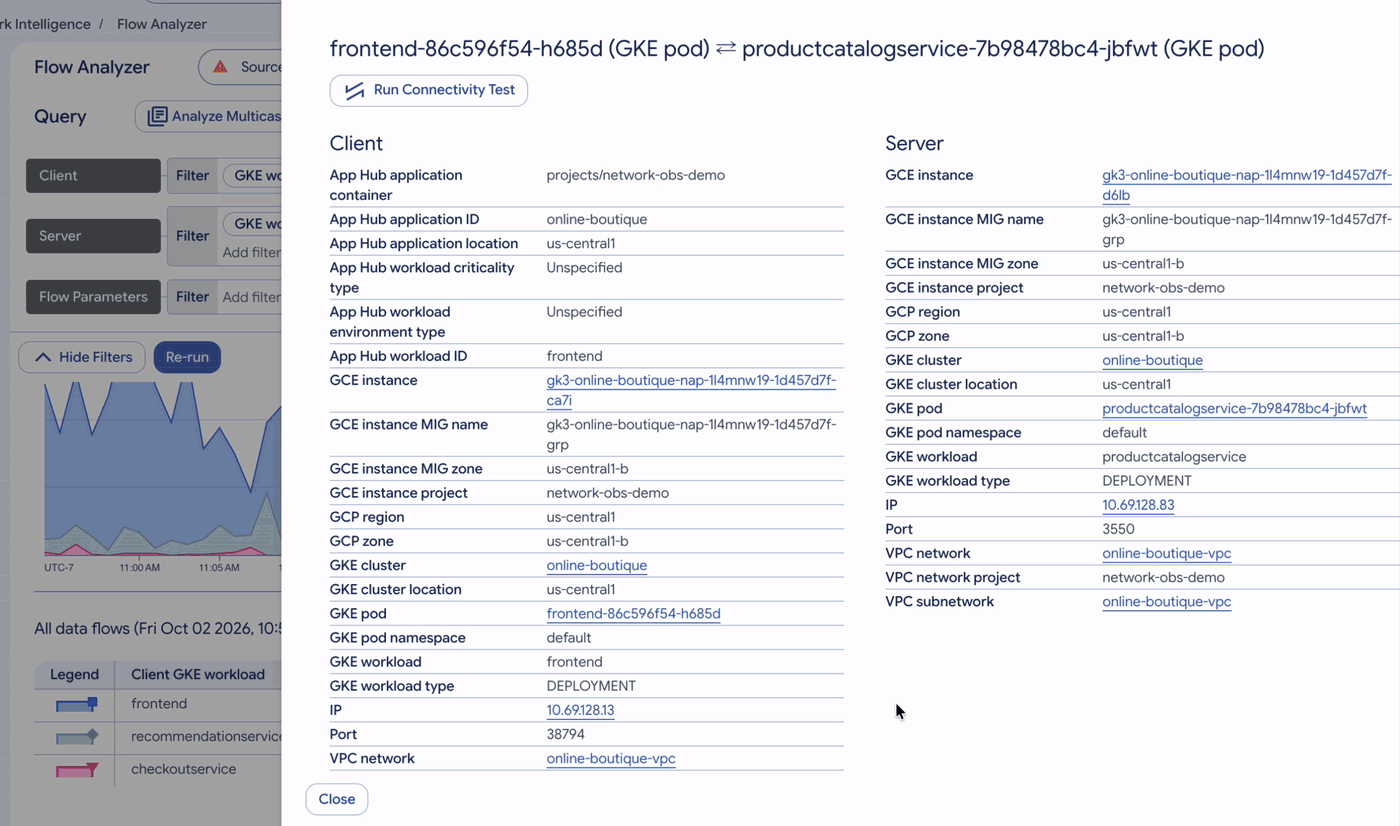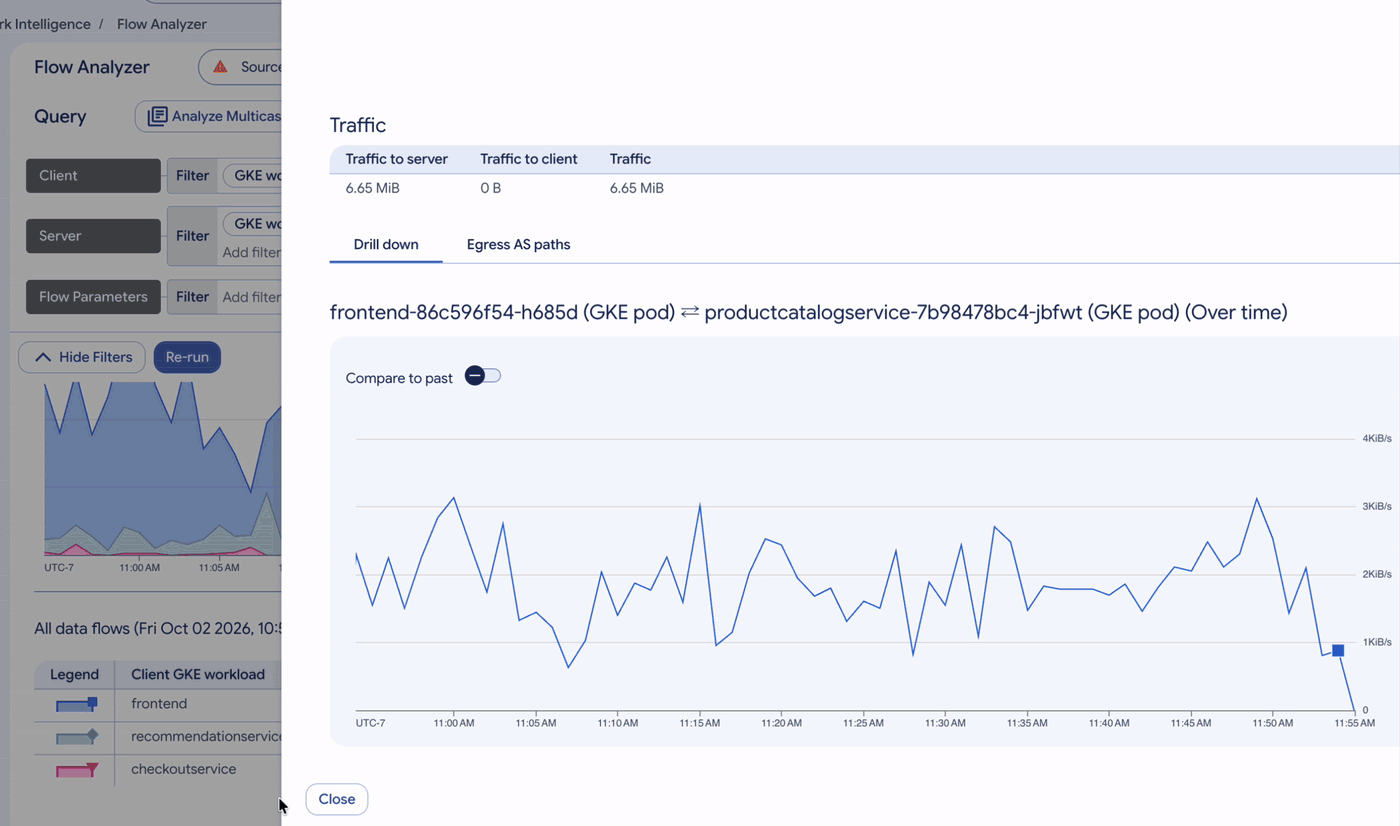
Key insights: You get every caller of the catalog service, each caller’s share of its traffic, and a timeline for every pair, so if one caller’s line climbs while the others stay flat, you know where to look first. When the question is latency rather than volume, switch the display mode to latency to rank the same callers by round-trip time.
Case 3: Find the pods that talk across zones
In a regional GKE cluster, chatty services that land in different zones send every request across a zone boundary, adding inter-zone data transfer charges. Because VPC Flow Logs record the zone at both ends of every flow, the pod pairs driving that traffic are easy to spot.
Steps in Flow Analyzer:
Switch from Basic filters to SQL filters, which let you compare two fields of the same flow.
In the WHERE box, enter src_gcp_zone dest_gcp_zone.
Set Organize flows by to Source GCP zone, Source GKE pod, Destination GCP zone, and Destination GKE pod.
Click Run new query.
Using SQL filters with src_gcp_zone dest_gcp_zone and multi-attribute grouping to identify pod pairs driving cross-zone network traffic.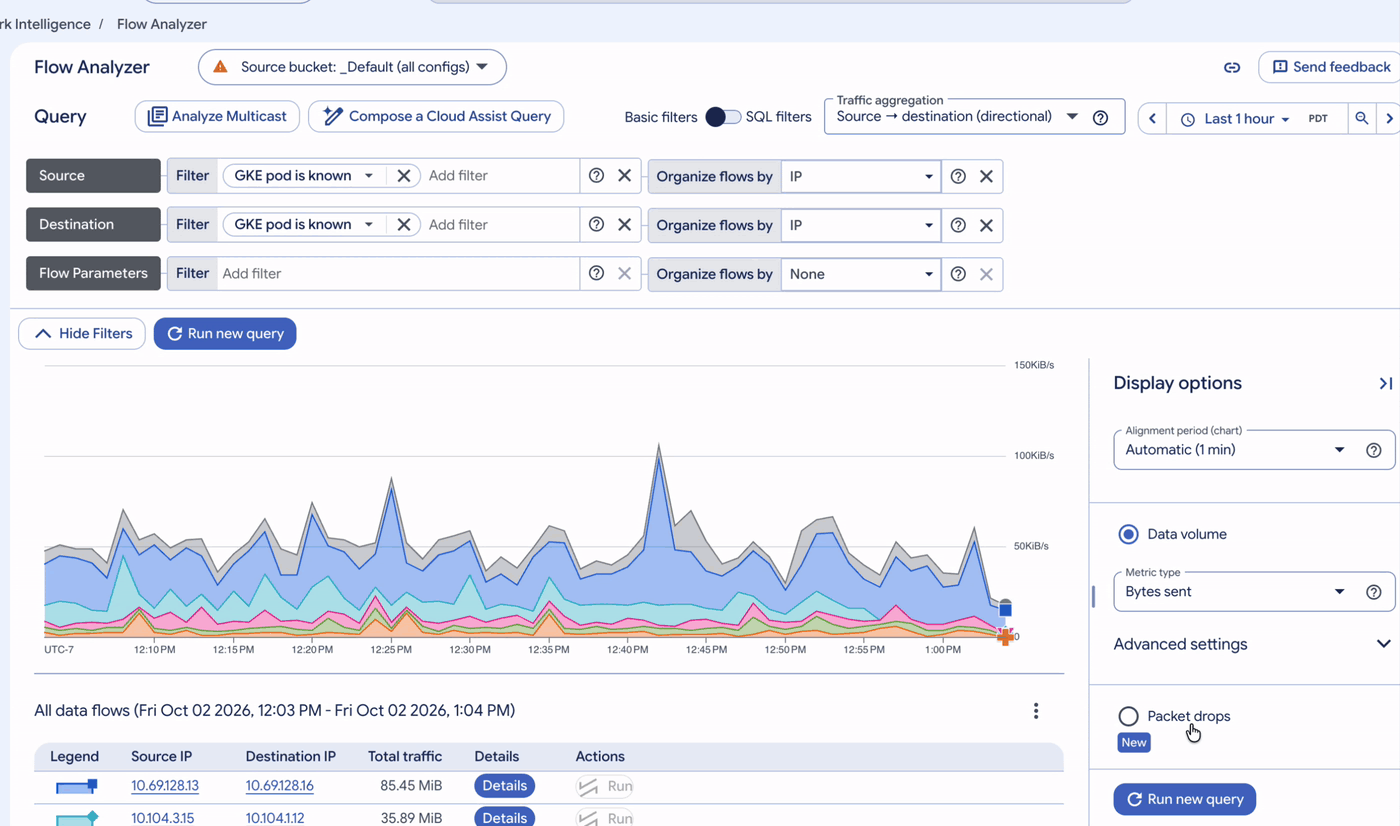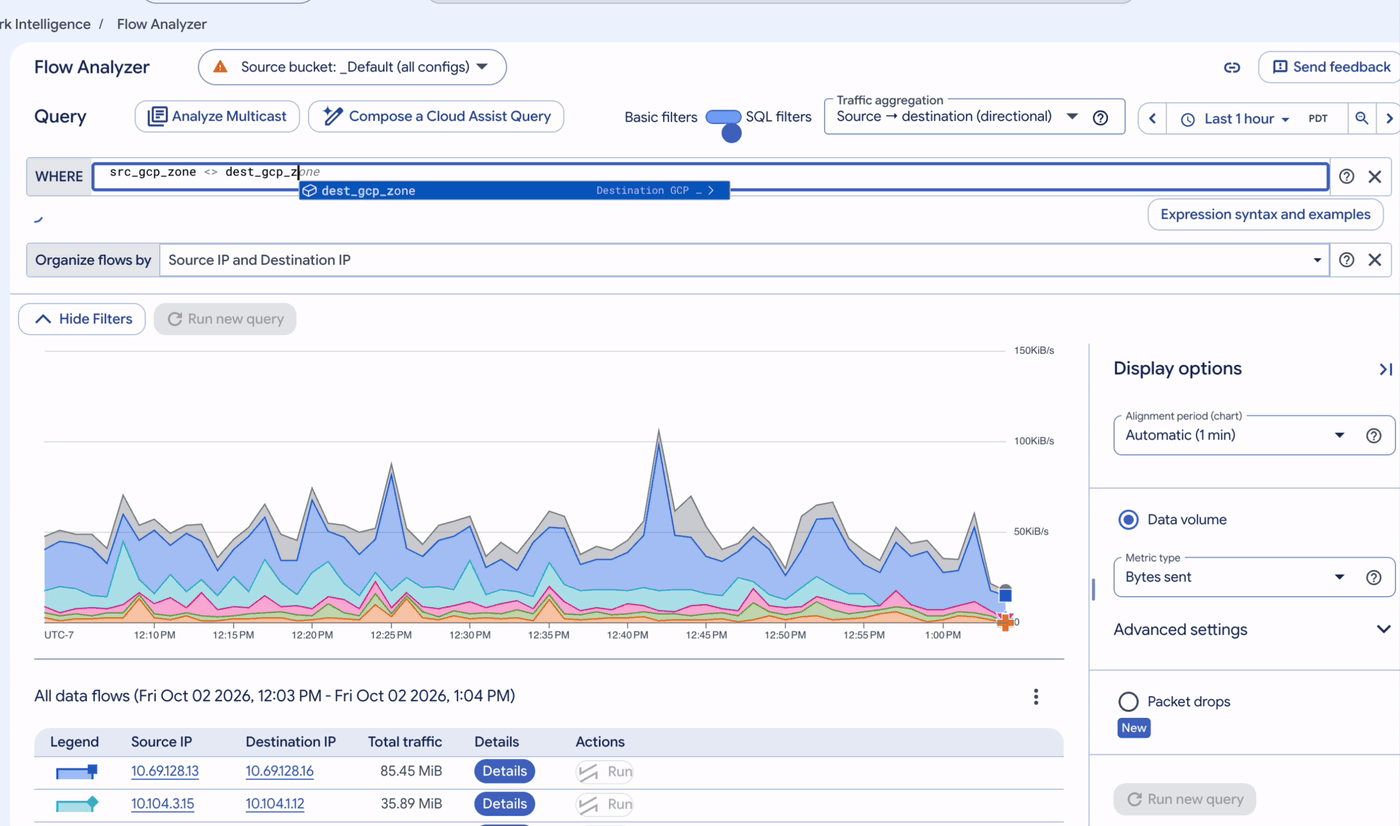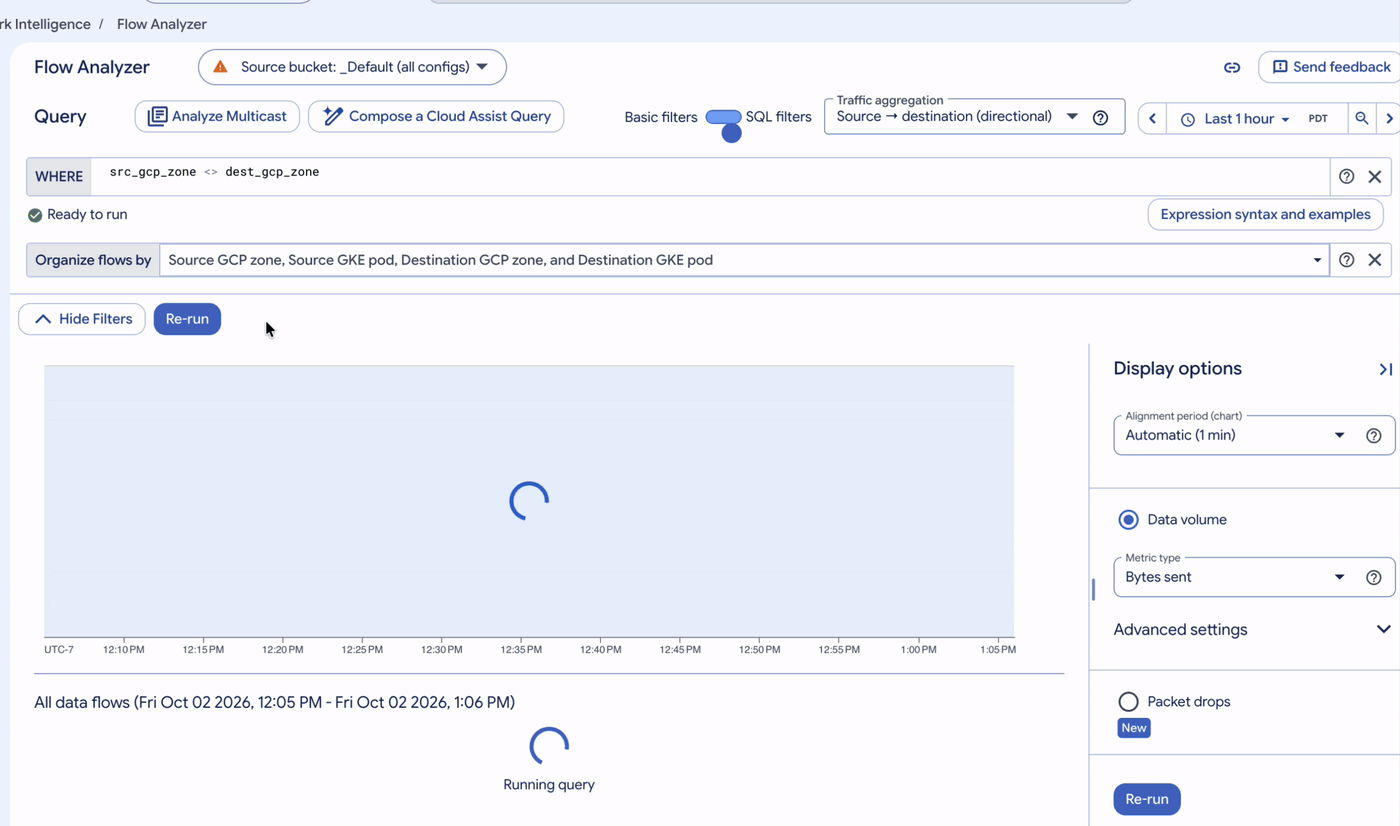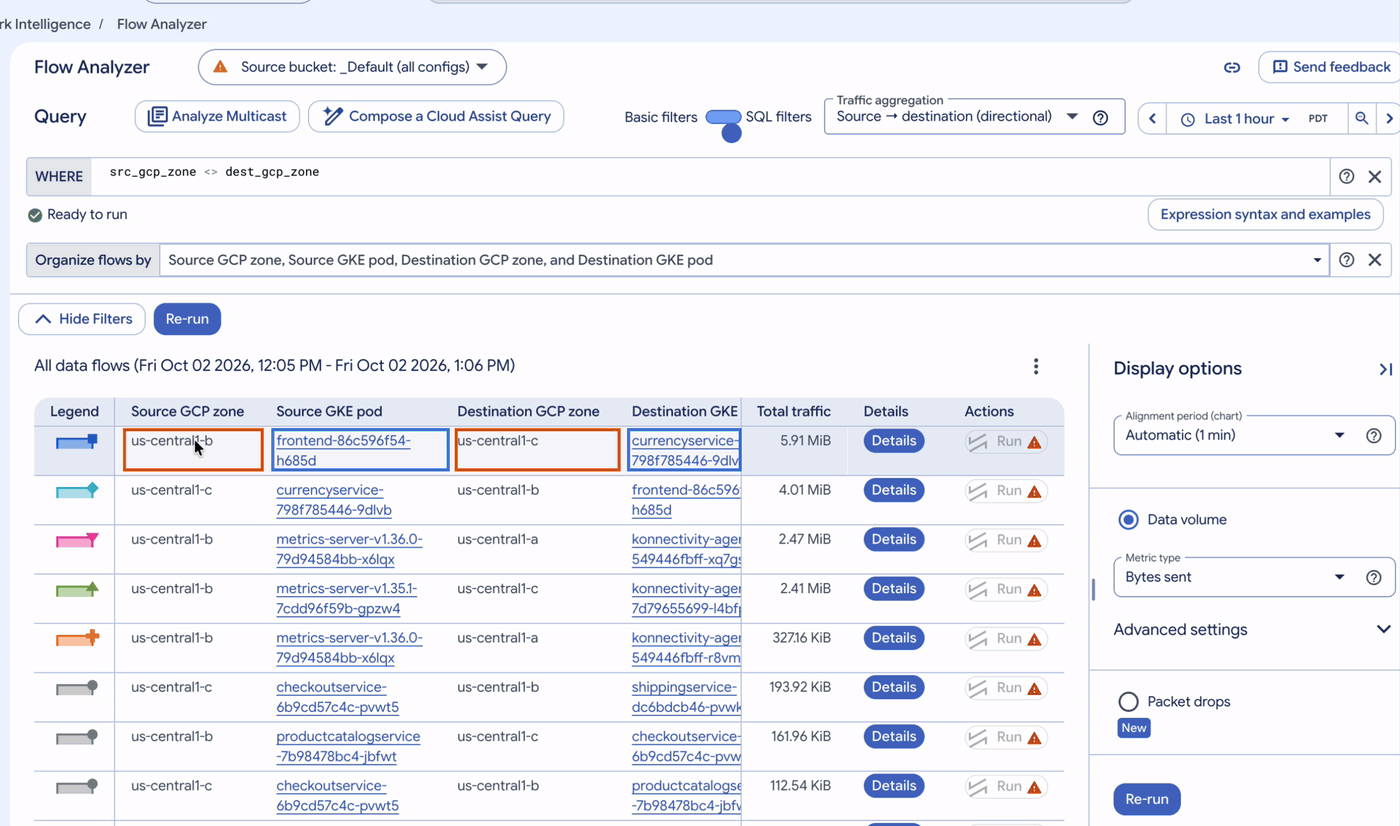
Key insights: The table displays cross-zone traffic ranked by volume, identifying the exact pods and zones on each end. In our cluster, the top flows occur between a frontend pod in us-central1-b and a currencyservice pod in us-central1-c, followed by checkoutservice, shippingservice, and productcatalogservice pairs. To investigate further, click Explore in Log Analytics to open the underlying SQL query for additional customization, such as adding joins or time buckets.
GKE has a built-in answer: set trafficDistribution: PreferSameZone (PreferClose on older versions) on the Service to prefer healthy endpoints in the caller’s zone, and make sure each zone has enough replicas to serve its own traffic.
Pod-to-internet traffic: VPC Flow Logs carry no pod annotations, because the masquerade agent replaces the pod IP with the node IP before the flow is sampled. Keeping internal destinations in the non-masquerade list preserves pod names for those flows, and if you run ip-masq-agent with intranode visibility, that list must also include the cluster’s node and pod IP ranges to avoid connectivity problems.
Blocked traffic: Traffic blocked by a network policy never reaches the VPC network, so use NetworkPolicy logging to investigate it.
Sampling: Flow logs are sampled, which makes byte and packet counts well suited for ranking and trending rather than per-connection accounting.
If your clusters already have VPC Flow Logs turned on, upgrading the _Default bucket and opening Flow Analyzer is all it takes to reproduce the three walkthroughs above. To learn more, see the documentation: